4.3.1 File-System Layout
File systems are stored on non-volatile disks, solid-state drives, or partitions. Physical storage devices divide raw media into fixed-size physical sectors (typically 512 bytes or 4096 bytes). Operating system file systems group these physical sectors into larger logical blocks (clusters), typically ranging from 1 KB to 64 KB, to balance metadata overhead against internal fragmentation.
4.3.2 Implementing Files: Allocation Strategies & Fragmentation
The central design challenge of a file system is mapping a linear stream of logical file bytes into physical storage blocks. Over time, file churn produces external and internal fragmentation.
4.3.5 Log-Structured File Systems (LFS)
Traditional Unix and FAT filesystems distribute file data, inodes, directory entries, and indirect blocks across random locations on disk. As processor and memory speeds outpaced mechanical disk seek times in the early 1990s, random disk head seeks emerged as the primary performance bottleneck. To solve this, Mendel Rosenblum and John K. Ousterhout pioneered Log-Structured File Systems (LFS) at UC Berkeley, fundamentally redesigning storage architectures by transforming the disk into a continuous sequential log.
Pioneers Profile: Mendel Rosenblum & John K. Ousterhout
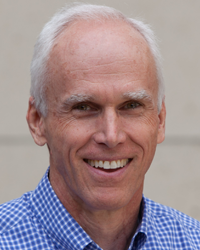
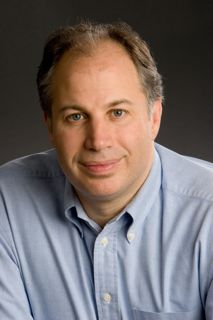
- Institution: University of California, Berkeley
- Key Publication: “The Design and Implementation of a Log-Structured File System” (ACM TOCS, 1992)
- Core Innovation: Replaced random in-place metadata and data updates with continuous sequential log writes, accompanied by inode maps and background segment cleaning.
1. The Log-Structured Paradigm & The Write Bottleneck
In traditional file systems (such as FFS or FAT), modifying a file requires multiple random disk I/O operations. Rosenblum and Ousterhout observed that caching absorbs reads, making writes the primary bottleneck. LFS buffers updates in memory and writes them out sequentially to segments.
2. The Inode Map (Imap) Architecture & Indirection
In traditional file systems, inode numbers map to fixed disk offsets. In LFS, inodes relocate on every append, requiring the Inode Map (Imap) indirection layer.
3. Checkpoint Regions & Rapid Crash Recovery
LFS breaks recursive imap indirection using fixed Checkpoint Regions (CRs). To prevent write tearing during power cuts, LFS alternates between dual regions (CR A and CR B), picking the most recent valid checksum upon reboot.
4. Background Garbage Collection & Segment Cleaning
Segment cleaning reclaims fragmented dead space using the Cost-Benefit policy ((1-u) × Age) / (1+u), balancing hot and cold data compaction.
4.3.6 Journaling File Systems & Write-Ahead Logging (WAL)
Traditional filesystems update structures directly in-place across scattered disk blocks. When a sudden power outage, kernel panic, or hardware disconnect occurs mid-write, the filesystem is caught midway through mutating interlinked records, producing severe metadata desynchronization.
Database Pioneers: Jim Gray & C. Mohan (Transaction Processing & WAL Theory)

To prevent lengthy multi-hour volume repair scans upon reboot (such as fsck), modern filesystems (including Linux ext3, ext4, XFS, and Windows NTFS) implement Write-Ahead Logging (WAL), universally referred to as Journaling.
1. The Crash Consistency Problem
A single high-level file modification rarely maps to a single physical disk write. Appending data to an existing file requires executing three distinct physical writes:
- Data Block Write: Writing user payload bytes into a newly allocated data block (D).
- Inode Metadata Update: Modifying the file's inode (I) to update file length, modification timestamps, and insert an address pointer referencing block D.
- Data Allocation Bitmap Update: Toggling the corresponding bit in the block allocation bitmap (B) from
0(free) to1(allocated) to prevent other files from claiming block D.
Physical storage controllers guarantee atomic writes strictly at the granularity of a single physical sector (typically 512 bytes or 4 KB). Atomic writes across three completely separate disk blocks located thousands of sectors apart are physically impossible. If the system loses power between any of these operations, the filesystem enters an inconsistent failure state:
- Crash after Inode (I), before Bitmap (B): The inode references block D, but the bitmap marks block D as free. When another process creates a file, the allocator will grant that exact same block D to the new file, producing block cross-allocation and catastrophic data theft.
- Crash after Bitmap (B), before Inode (I): Block D is marked occupied in the bitmap, but no inode in the entire file system points to it. This creates a permanent, silent storage space leak.
- Crash after Inode (I), before Data (D): The inode points to block D, but block D was never written. Reading the file returns uninitialized remnants of whatever deleted data resided in that sector previously, causing data corruption and severe security information leakage.
2. The Write-Ahead Logging (WAL) Protocol
Journaling solves this vulnerability by importing the Write-Ahead Logging (WAL) protocol from relational database engines. The governing invariant of Write-Ahead Logging is absolute:
The Fundamental WAL Rule: Never overwrite or update the permanent in-place filesystem structures on disk until a complete description of the impending changes has been sequentially logged, flushed to non-volatile media, and anchored by an explicit, atomic commit record.
Rather than writing directly to the permanent inode tables and allocation bitmaps, the operating system routes modifications through a dedicated, contiguous circular ring buffer called the Journal (or log).
The Anatomy of a Journal Transaction
Related updates are bundled together into an atomic container called a Transaction. A transaction proceeds through four chronological stages:
- Transaction Header (Tx Begin): A special descriptor block containing a unique monotonically increasing Transaction ID (TID), starting timestamp, and a manifest of the dirty metadata blocks scheduled for modification.
- Descriptor & Payload Blocks: The operating system writes exact in-memory copies of the updated inode (I), the updated allocation bitmap (B), and any modified directory blocks into the sequential journal stream.
- Write Barrier & The Commit Block: The controller issues a strict hardware write barrier (e.g.,
FLUSH CACHEorFUA– Force Unit Access) to ensure all payload blocks are physically seated on persistent media. Only then does it append the Commit Block. The commit block contains the matching Transaction ID and a cryptographic/CRC32 checksum of the entire transaction payload. The instant this commit block reaches disk, the transaction is durable. - Checkpointing (In-Place Flushing): With the transaction safely recorded in the journal, the operating system writes the modified blocks out to their permanent locations across the disk (the real inode table, the real bitmap).
- Transaction Release (Journal Free): Once in-place checkpointing finishes, the circular journal marks that transaction's ring buffer sectors as reclaimed, advancing the journal head pointer.
4.3.7 Flash Storage & Wear-Leveling Systems
Flash memory cannot overwrite in place due to the erase-before-write constraint. The Flash Translation Layer (FTL) handles out-of-place writes, garbage collection, and dynamic/static wear leveling.
TRIM notification to invalidate dead records, and observe how Static Wear-Leveling moves cold data to preserve flash cells.
4.3.8 Virtual File Systems (VFS)
A contemporary Unix or Linux installation concurrently manages dozens of radically different storage targets: local journaling filesystems (ext4, XFS), legacy FAT volumes on USB drives (vfat), remote network shares (NFS, SMB), optical disc structures (ISO 9660), and volatile kernel introspection pseudo-filesystems (procfs, sysfs).
If user applications were required to invoke unique, driver-specific system calls for every storage target (e.g., ext4_read(), nfs_read(), fat_read()), application portability would collapse. To deliver a seamless, uniform programming model, modern operating systems implement the Virtual File System (VFS) abstraction layer. Originally pioneered by Sun Microsystems in 1985 to integrate NFS into SunOS, VFS provides an object-oriented polymorphic interface in C that decouples standard POSIX system calls from concrete storage implementations.
1. The Polymorphic VFS Architecture
The core design principle of VFS is polymorphism: user processes execute generic POSIX system calls (open(), read(), write(), close(), stat()), which route directly into the VFS layer. The VFS layer contains generic algorithms for path navigation, security validation, and buffer caching.
When an action requires interacting with concrete storage, VFS dispatches the call through function pointer tables registered by the specific filesystem driver mounting that path.
2. The Four Primary VFS Data Objects
The Linux VFS architecture defines four core data structures that model every filesystem concept in memory:
1. The Superblock Object (struct super_block)
Represents an entire mounted filesystem instance. It holds filesystem-wide parameters, such as block size, device identifiers, mount flags, and a pointer to the root dentry. Crucially, it stores the s_op pointer pointing to Superblock Operations:
alloc_inode(): Allocates memory for a new in-core inode structure.write_inode(): Flushes modified inode metadata from memory to storage.sync_fs(): Flushes dirty filesystem superblocks and metadata to disk.statfs(): Queries filesystem storage statistics (free blocks, total capacity).
2. The Inode Object (struct inode)
Represents a specific file, directory, socket, or device node uniquely within a filesystem. Unlike disk inodes, a VFS inode exists entirely in memory and contains file size, owner UID/GID, permission bits, access/modification timestamps, and locks. It holds two sets of operation tables:
i_op(Inode Operations): Structural operations that manipulate file namespace and links, such aslookup(),create(),link(),unlink(),mkdir(), andrename().i_fop(Default File Operations): Fallback file manipulation methods assigned when a file is opened.
3. The Dentry Object (struct dentry)
In Unix, inodes contain metadata and block pointers, but no file names. File names exist solely as entries within directory payloads. To enable high-speed string path resolution, the VFS introduces Directory Entries (dentries).
A dentry represents a single path component (e.g., in /usr/bin/python3, there are dentries for /, usr, bin, and python3). Each dentry links a string name to its corresponding struct inode. Dentries are cached in the high-speed kernel Dentry Cache (Dcache).
4. The File Object (struct file)
Represents a dynamic, open file descriptor instantiated when a user space thread invokes open(). While an inode represents the static file on disk, a struct file represents an active interaction context. It stores:
f_pos: The current byte seek offset of the process within the file.f_flags: Open status flags (e.g.,O_RDONLY,O_APPEND,O_NONBLOCK).f_count: Atomic reference counter tracking how many processes share this descriptor (e.g., post-fork()).f_op: Pointer to the File Operations table containing the implementation functions:read(),write(),mmap(),llseek(), andfsync().
3. Path Resolution & The Dentry Cache (Dcache)
Looking up a path such as /usr/bin/gcc requires stepping down directory structures. The VFS accelerates this through the in-memory Dentry Cache (Dcache):
- Hash Table Lookup: The kernel hashes
(parent_dentry, "child_name")and queries a global hash table. - Dcache Hit: If cached, VFS retrieves the associated
struct inodelocklessly via Read-Copy-Update (RCU). - Dcache Miss: If not cached, VFS invokes the driver's
inode->i_op->lookup()method, reading directory blocks from storage and inserting the new dentry into the cache. - Mount Point Traversal: If a traversed dentry has the
DCACHE_MOUNTEDflag, VFS seamlessly redirects lookup to the root dentry of the mounted filesystem's superblock.